UK estate agent AI visibility benchmark
Scanned August–September 2026 · updated 3 October 2026
We scanned 10 UK estate and letting agents. The first question a vendor asks is what the fee is, and an assistant cannot answer it for most of them.
- Median score
- 62.9
- Range
- 53.2–76.4
- Businesses scanned
- 10
- Worth per customer
- £3,500
Fees and terms score 0.30 — the question every vendor asks first
The spread is the story. When a third of the field is 20 points clear, being invisible is a choice rather than a constraint.
True in every vertical
Three findings held across all 82 businesses we scanned, regardless of industry:
| Check | Score | What it means |
|---|---|---|
| Agentic commerce endpoints | 0.00 | Not one business of 82 exposes an ACP or AP2 surface. An assistant cannot transact with any of them directly. |
| llms.txt guidance file | ~0.15 | Almost nobody publishes one. It is free to add and takes minutes. |
| Structured data (schema.org) | 0.25–0.32 | The single biggest scoring gap in every vertical. Without it an assistant has to infer what the business even is from prose. |
What this measures, in fourteen seconds
Where does your site sit?
The same audit, run on your own domain. One field, about twenty seconds, no account and no card.
Run the free check →How this was measured
Each site was scanned by an automated audit that scores nine weighted checks: crawler access, structured data, whether content survives without JavaScript, machine-readable pricing, bot protection, terms and security, an llms.txt guidance file, sitemap discoverability, and agentic commerce endpoints. The score is out of 100.
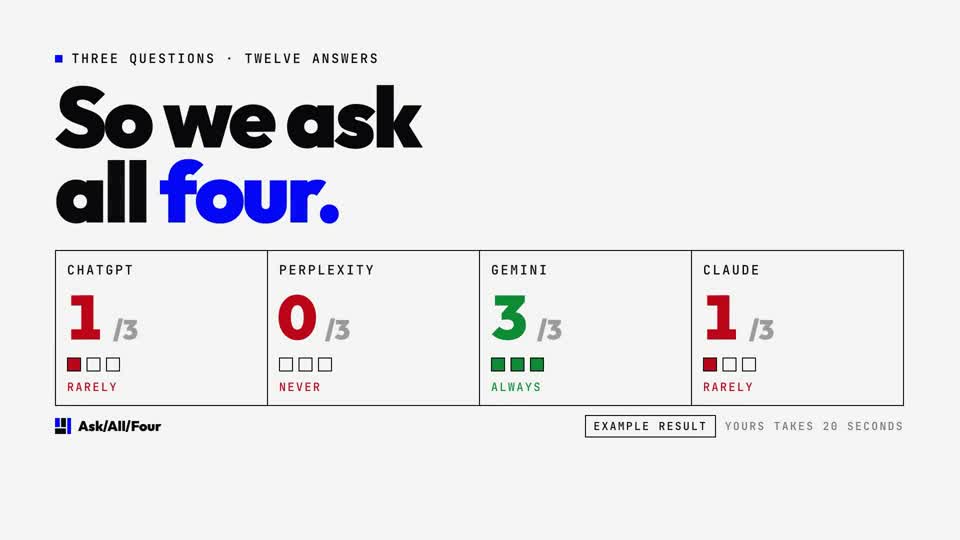
This measures what a machine can read on the public website. It is a separate question from whether an assistant actually names the business when asked — that is measured by putting real questions to ChatGPT, Perplexity, Gemini and Claude, and the two do not always agree.
This sample is small. At n=10 the median is indicative, not authoritative — we publish it with the sample size attached rather than rounding it into a claim it cannot support. We are extending this corpus to around 25 before treating the figure as firm.
n = 10 · scanned August–September 2026 · no business named
The other verticals
- Wedding venues — median 64.5, n=21
- Solicitors — median 68.2, n=9
- Hotels — median 55.5, n=30